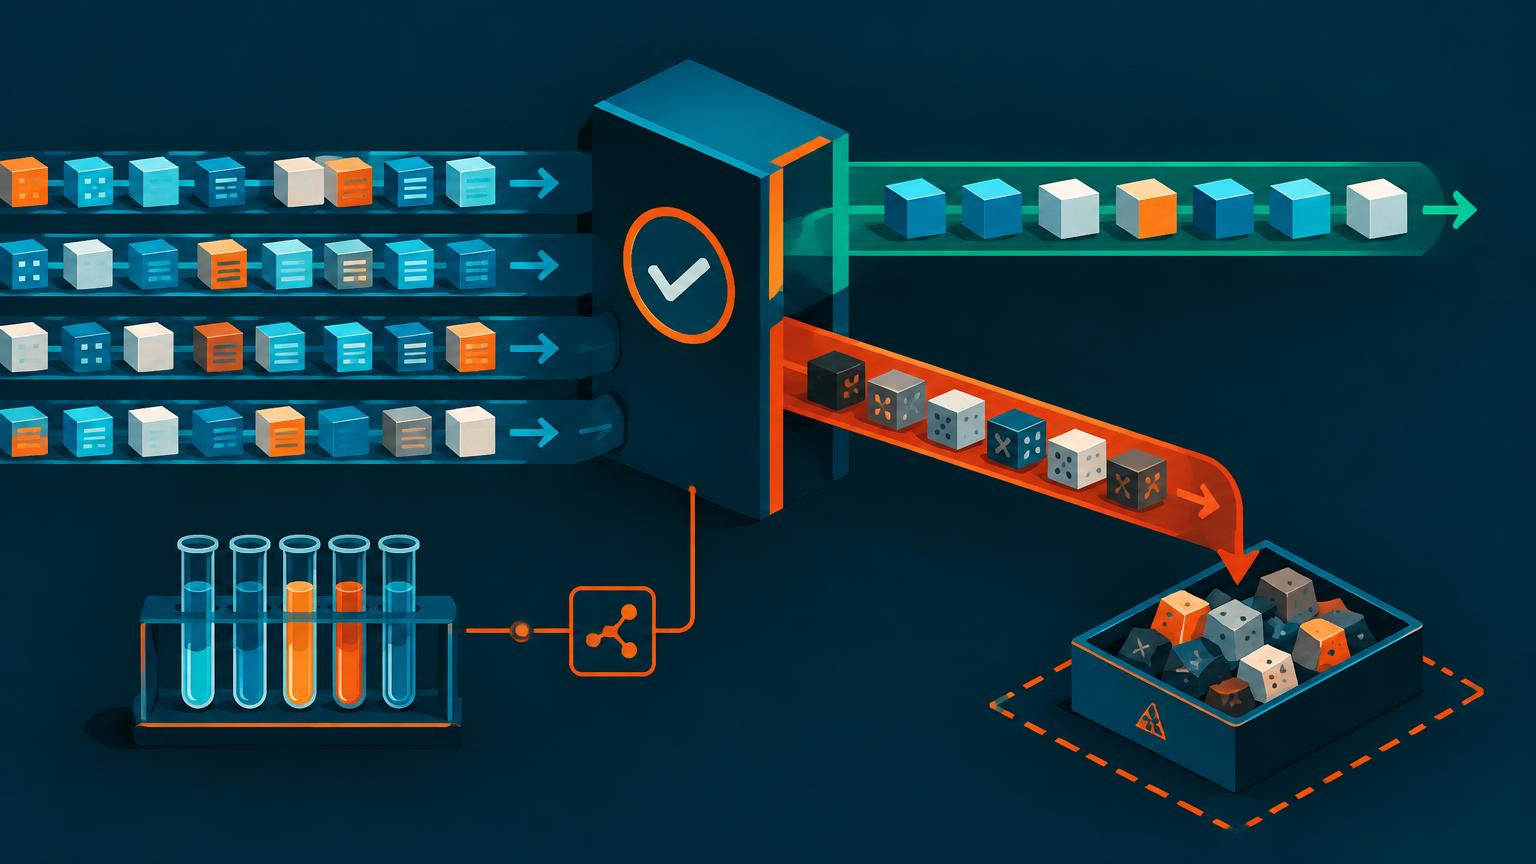
Notebook code that “looks right” on a sample is the most common source of wrong dashboards. The fix is boring and effective: move logic into functions, test them on handcrafted rows, and check data quality on every run.
Refactor into a pure function
transforms.pyPython
1from pyspark.sql import DataFrame, Window, functions as F2 3def sessionize(df: DataFrame, gap_seconds: int = 1800) -> DataFrame:4 order_columns = ["event_ts"] + [5 name for name in ("title_id", "event_type", "watch_seconds")6 if name in df.columns7 ]8 w = Window.partitionBy("viewer_id").orderBy(*order_columns)9 return (10 df.withColumn("prev_ts", F.lag("event_ts").over(w))11 .withColumn("new_session", F.when(12 F.col("prev_ts").isNull() |13 (F.col("event_ts").cast("long") - F.col("prev_ts").cast("long") > gap_seconds), 114 ).otherwise(0))15 .withColumn("session_n", F.sum("new_session").over(16 w.rowsBetween(Window.unboundedPreceding, 0)))17 .drop("prev_ts", "new_session")18 )Test with rows you can read
test_transforms.pyPython
1from datetime import datetime2from pyspark.testing import assertDataFrameEqual3from transforms import sessionize4 5def test_gap_starts_new_session(spark):6 t = lambda m: datetime(2026, 10, 1, 20, m)7 df = spark.createDataFrame(8 [(1, t(0)), (1, t(10)), (1, t(55)), (2, t(0))],9 "viewer_id int, event_ts timestamp")10 11 got = sessionize(df).select("viewer_id", "event_ts", "session_n")12 expected = spark.createDataFrame(13 [(1, t(0), 1), (1, t(10), 1), (1, t(55), 2), (2, t(0), 1)],14 "viewer_id int, event_ts timestamp, session_n bigint")15 16 assertDataFrameEqual(got, expected)A spark pytest fixture with SparkSession.builder.master("local[1]") keeps tests fast and deterministic. Include edge cases deliberately: a single event, identical timestamps, and a gap exactly equal to the threshold. Order timestamp ties by title_id, event_type, and watch_seconds where available; tiny fixtures without those columns still work. Keep the strict > 1800 rule: a gap of exactly 1,800 seconds does not start a new session.
Expectations in the pipeline
quality.pyPython
1CHECKS = {2 "viewer_id_present": F.col("viewer_id").isNotNull(),3 "known_event_type": F.col("event_type").isin("start", "pause", "resume", "complete"),4 "watch_in_range": F.col("watch_seconds").between(0, 6 * 3600),5}6 7def apply_checks(df):8 flagged = df9 for name, cond in CHECKS.items():10 flagged = flagged.withColumn(f"ok_{name}", F.coalesce(cond, F.lit(False)))11 ok = F.expr(" AND ".join(f"ok_{n}" for n in CHECKS))12 return flagged.filter(ok), flagged.filter(~ok)13 14valid, rejected = apply_checks(good)15failure_rate = rejected.count() / max(good.count(), 1)16assert failure_rate < 0.01, f"Quality gate failed: {failure_rate:.2%}"Exercises
- Add a test for a gap exactly equal to gap_seconds and decide the intended behavior.
- Write a check that event_ts is not in the future and add a failing fixture row.
- Report per-check failure counts instead of one combined rate.
- Run your tests in CI with a pinned PySpark version.
Official documentation