Reading path
All eight chapters
 019 min read
PySpark Mental Model: Lazy DataFrames for Media Analytics
Learn the PySpark mental model with a synthetic streaming-media dataset: DataFrames, lazy transformations, actions, and reading a query plan.
Read chapter 029 min read
PySpark Ingestion: Explicit Schemas and a Delta Bronze Table
Ingest synthetic playback JSON with explicit PySpark schemas, capture malformed records, and write an append-only Delta bronze table.
Read chapter 0310 min read
PySpark Window Functions: Viewer Sessions and Completion Rates
Use PySpark window functions to sessionize synthetic viewer events, join a title catalog, and compute watch time and completion rates.
Read chapter 049 min read
Spark Performance: Shuffles, Partitions, and Broadcast Joins
A practical Spark performance guide using synthetic media data: shuffles, partition sizing, skew, broadcast joins, and adaptive query execution.
Read chapter 0510 min read
Spark Structured Streaming: Watermarks and Concurrent Viewers
Build Spark Structured Streaming windows and watermarks on synthetic playback events, with checkpoints and a per-minute heartbeat activity proxy.
Read chapter 069 min read
Testing PySpark Pipelines: Data Quality Checks That Catch Bugs
Test PySpark transformations with small synthetic DataFrames, assertDataFrameEqual, and explicit data quality expectations for media events.
Read chapter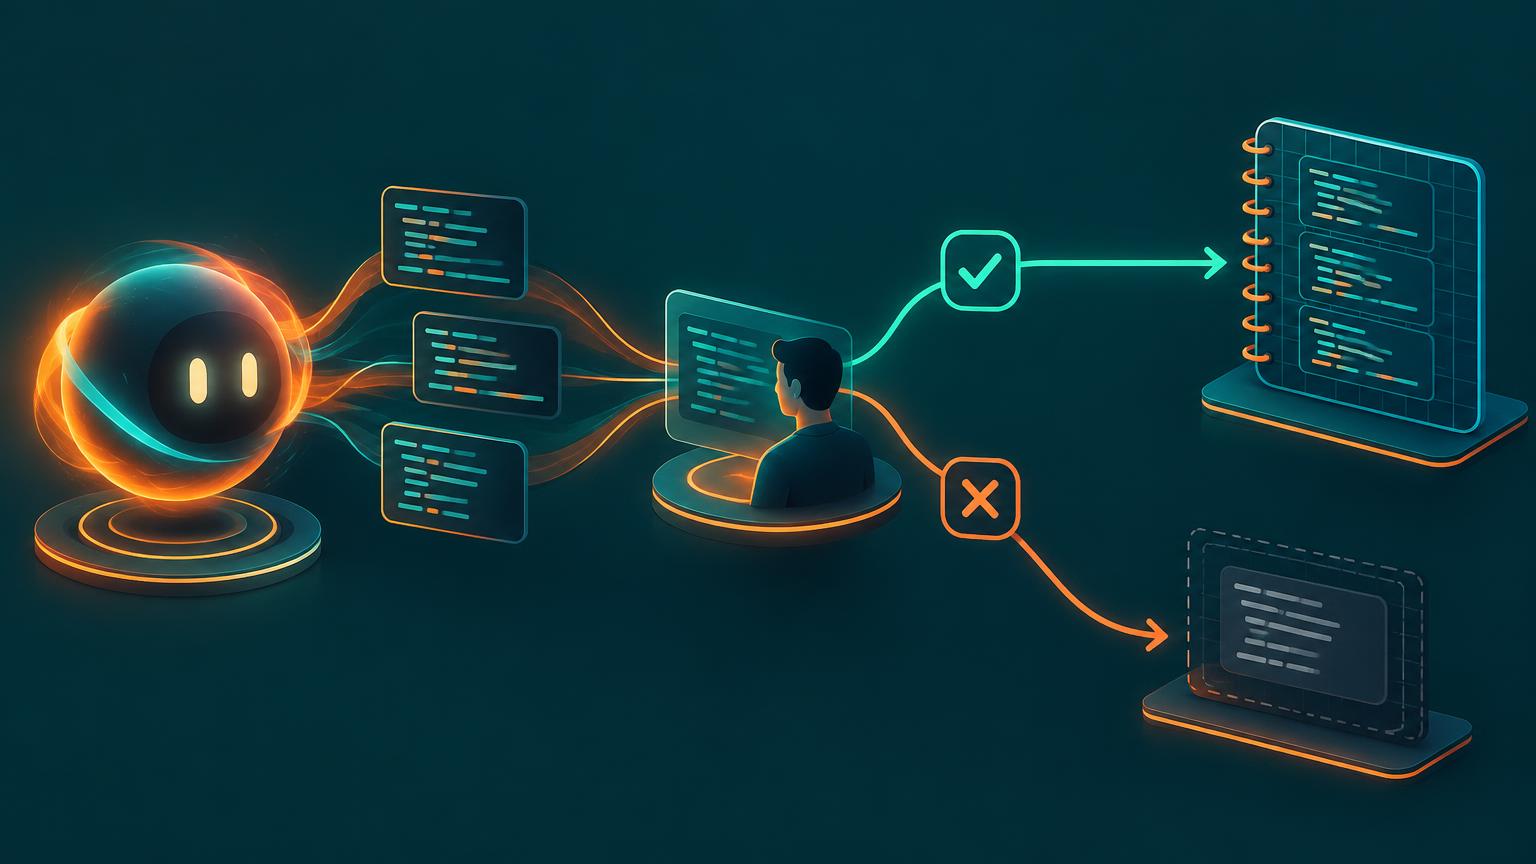 079 min read
Databricks Genie Code for PySpark: A Review-First Workflow
A practical workflow for Databricks Genie Code with PySpark: clear prompts, Unity Catalog context, reviewing generated code, and verifying results.
Read chapter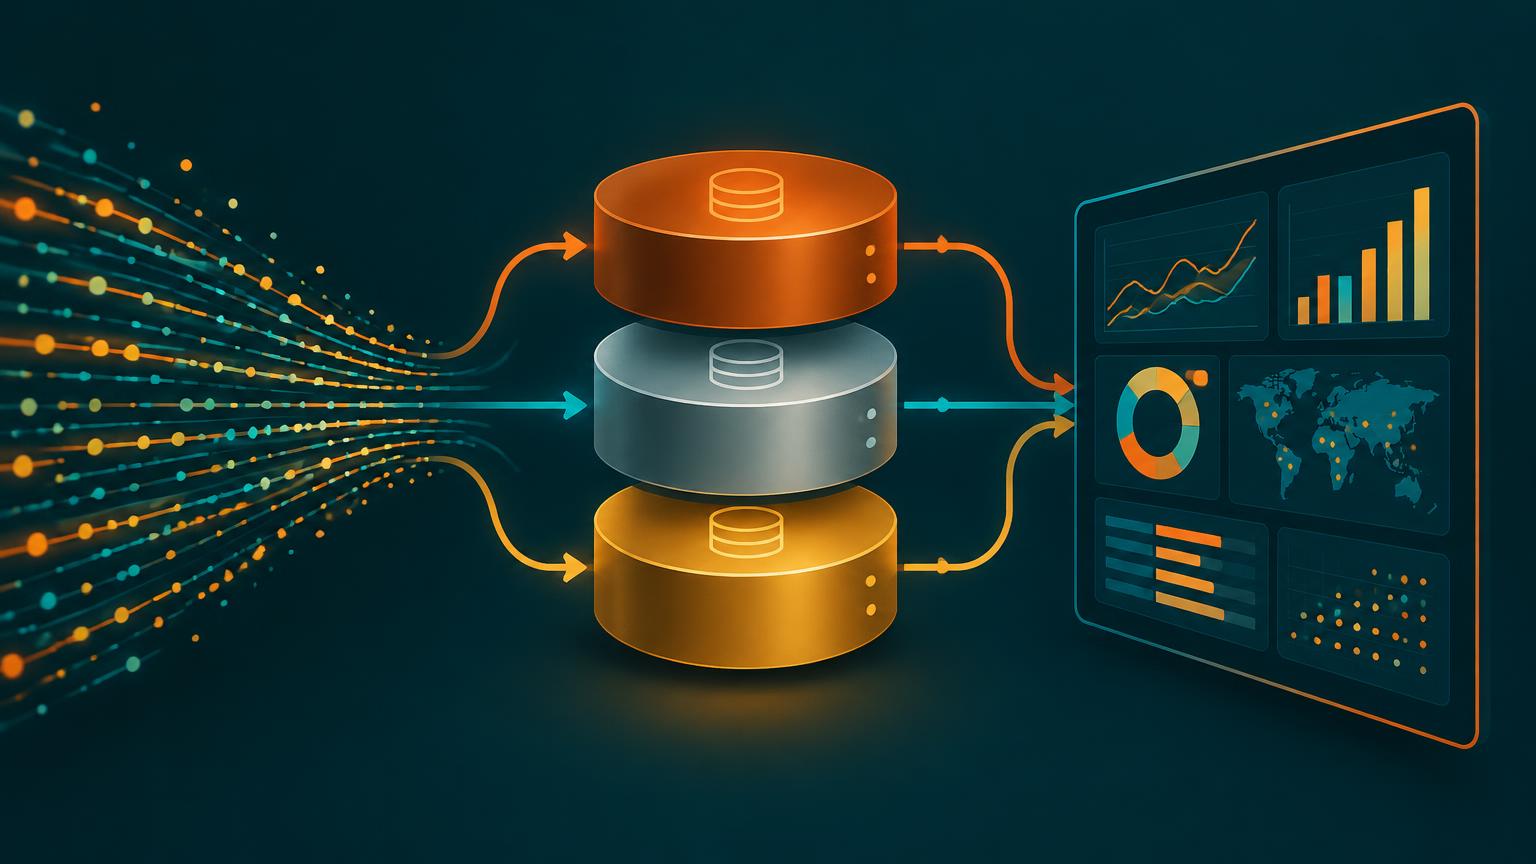 0810 min read
Capstone: An End-to-End Spark Medallion Pipeline for Media Data
Combine ingestion, sessionization, quality checks, and streaming into a bronze-silver-gold Spark pipeline on synthetic streaming-media data.
Read chapter
Companion lab
Run every chapter locally with synthetic data
All writing on PFP Labs is personal and independent. Databricks and Apache Spark are named for their technology; this series is not affiliated with or endorsed by any vendor. All data in the series is synthetic.
New posts, straight from Chris
A short note from me whenever a new article goes live — product engineering, AI workflows, IoT, indie apps, and engineering leadership. No spam, unsubscribe anytime.
By subscribing, you agree to our Privacy Policy. We do not share your email.