This is the optional foundations on-ramp to Spark for Streaming Media Analytics. Start here if driver, executor, partition, or shuffle still feels abstract. Already comfortable with those ideas? Jump to part one: the PySpark mental model and the runnable lab.
Imagine a fitness application that stores activity records. Each record contains an activity type, a date, and a duration. A small file is easy to analyze: load it, group the rows, and calculate totals.
Now imagine the same calculation across years of records spread over thousands of files. Reading and processing everything on one machine might take too long or exceed its available memory. How could several machines share the work without requiring you to coordinate every exchange yourself?
Apache Spark addresses that problem. It is an open-source data processing engine that can distribute computation across a cluster. You describe a transformation, and Spark plans and schedules the work. It can also run locally, which makes it possible to learn the same ideas on a laptop. Apache Spark FAQ
For a beginner, the most useful starting point is understanding where the data lives, who coordinates the work, and what happens when data has to move.
Where Spark fits in a data pipeline
Consider a daily report showing total activity minutes by activity type. The pipeline might look like this:
- Read activity records from storage.
- Remove invalid durations and select the required columns.
- Group the records by activity type.
- Write the totals for a dashboard to read.
Spark handles the processing in the middle. The input and output can live in external systems, including object storage, distributed filesystems, or databases accessed through suitable connectors. Spark does not require Hadoop, although it can work with Hadoop components. Apache Spark FAQ
That separation matters. Choosing Spark does not decide where your application stores its records or how your dashboard serves queries. Those are separate parts of the system.
Spark can cache reused data in memory, but memory is only one part of its execution model. Processing can involve disk reads, disk writes, and network transfers. A useful first question is therefore: where will this calculation spend its time? RDD programming guide
Partitions let several workers share the work
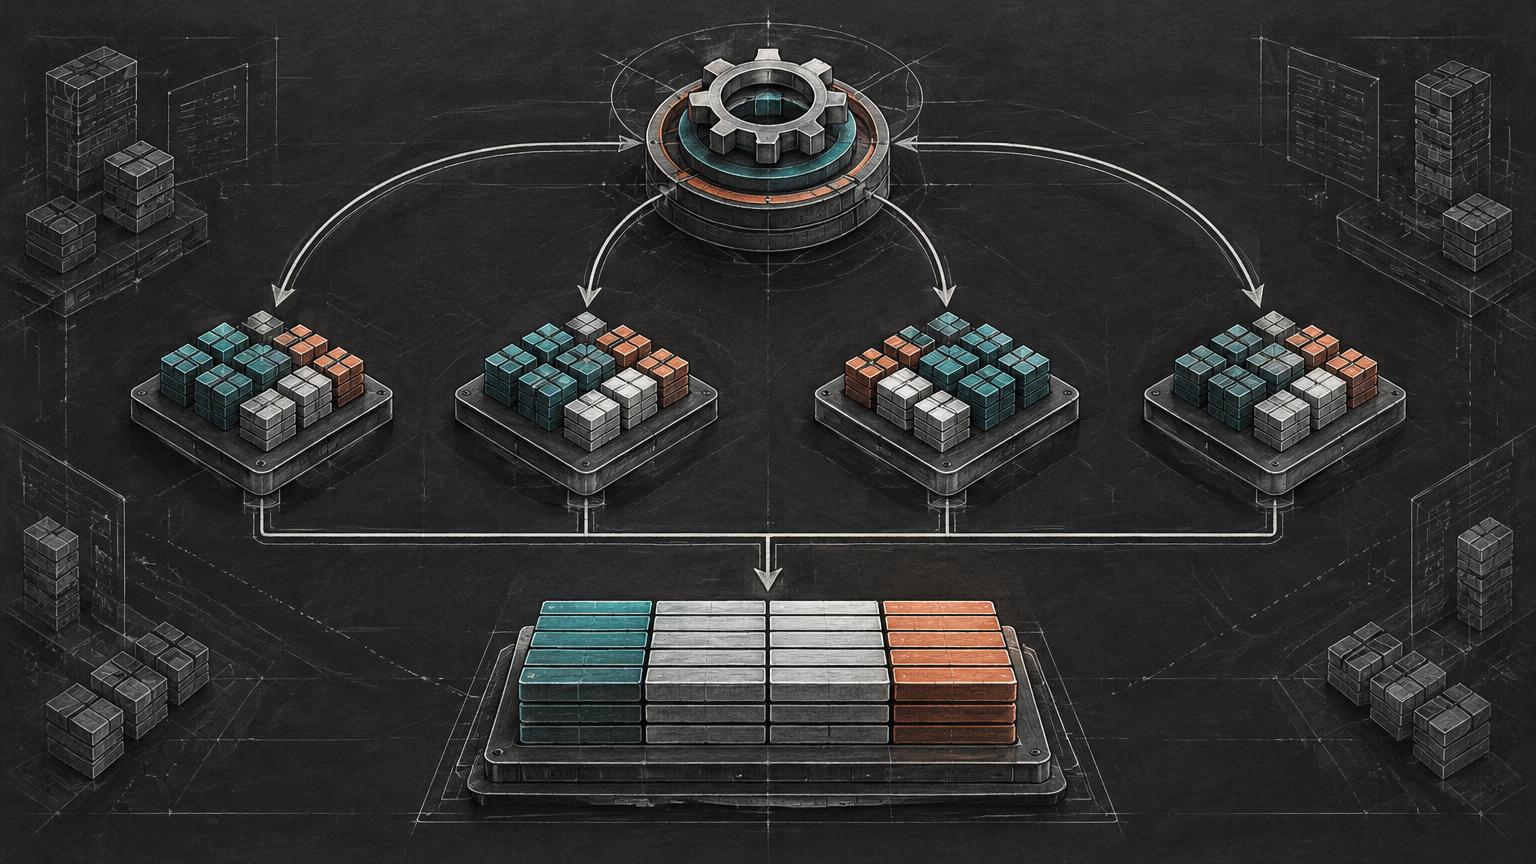
Spark divides distributed data into partitions: chunks that can be processed separately. For our activity report, different partitions might contain different subsets of the records.
Three terms explain the basic architecture:
- Driver: the process that coordinates the application and schedules its work.
- Executors: processes that run tasks and hold application data in memory or on disk.
- Cluster manager: the component that allocates resources to applications.
An executor is a process, so it should not be confused with an entire machine. A task is a unit of work sent to an executor; within a stage, a task processes a partition. Available resources determine how many tasks run at once. Extra partitions can wait their turn. Cluster mode overview
Picture four people sorting boxes of activity records. Giving each person a box allows parallel work. Giving one person an enormous box while the others receive tiny ones leaves most of the team waiting. This uneven distribution is an important performance problem to recognize later.
One application. Many tasks.
- 01
Cluster manager
Allocates resources
- 02
Driver
Plans and schedules tasks
- 03
Executors
Processes that run tasks
- 04
Partitions
Logical slices of data
DataFrames describe the calculation
A common starting point is a DataFrame, a distributed collection organized into named columns. Its schema describes the columns and their types.
With PySpark, you use Python to build DataFrame expressions. You can also express transformations in SQL. Both interfaces use Spark SQL's execution engine, so learning SQL concepts such as filtering, grouping, and joining transfers well to Spark. Spark SQL and DataFrames
DataFrame transformations are generally lazy. Calling a filter or selecting columns builds a plan rather than immediately performing the full computation. An action, such as displaying results, collecting them, or writing output, requests execution. Some preparation, such as reading metadata or inferring a schema, can happen earlier. PySpark DataFrame quickstart
Here is a small illustrative example. It has not been executed for this article. It assumes a working PySpark environment and uses invented records entirely in memory.
1from pyspark.sql import SparkSession, functions as F2 3spark = SparkSession.builder.appName("activity-totals").getOrCreate()4 5activities = spark.createDataFrame(6 [("run", 30), ("walk", 20), ("run", 45), ("walk", -5)],7 schema="activity_type string, duration_minutes int",8)9 10valid = activities.filter(F.col("duration_minutes") > 0)11 12totals = valid.groupBy("activity_type").agg(13 F.sum("duration_minutes").alias("total_minutes")14)15 16totals.show()The intended result is 75 minutes for running and 20 for walking. The negative duration is excluded. Row order is unspecified because the query does not request a sort.
The same calculation can be expressed in SQL after registering the DataFrame as a temporary view:
1activities.createOrReplaceTempView("activities")2 3spark.sql("""4 SELECT activity_type, SUM(duration_minutes) AS total_minutes5 FROM activities6 WHERE duration_minutes > 07 GROUP BY activity_type8""").show()For a real pipeline, replace the tiny in-memory input with an appropriate data source and write the result to a suitable destination. The transformation itself remains recognizable.
Jobs and stages explain execution
When computation is requested, Spark schedules work as jobs, breaks jobs into stages, and runs tasks within those stages. A stage groups work that can proceed together without crossing the next required shuffle boundary. One action should not be assumed to produce exactly one job in every situation. Cluster mode overview
You may also encounter DAG, short for directed acyclic graph. It represents dependencies flowing from earlier operations to later ones without looping back. This helps explain why some work must finish before other work can begin. Spark Web UI guide
For our report, each partition can filter invalid durations independently. Producing a final total for each activity type requires combining information across partitions. That brings us to a central Spark concept: the shuffle.
From a question to distributed work
- 01
Action
Requests a result
- 02
Jobs
Scheduled computation
- 03
Stages
Separated by shuffle boundaries
- 04
Tasks
Process partitions in parallel
Shuffles move data to where it is needed
A shuffle redistributes data between partitions. Grouping, sorting, and many joins can require this movement. Shuffles can involve network traffic, serialization, and disk activity, making them an important source of cost. Shuffle operations
In the activity example, Spark can calculate partial sums before exchanging results. It does not necessarily send every original row across the network. For joins, the chosen strategy matters too: a small lookup table may be broadcast to workers instead of shuffling both sides. SQL performance tuning
The unequal-box problem is called skew. If one grouping or join key accounts for a disproportionate amount of work, a few tasks can take much longer than the rest. Adding machines may leave that imbalance largely intact. Spark has adaptive optimizations for some cases, but inspecting the execution plan and task behavior is still valuable. SQL performance tuning
Another common mistake is moving a large result back to one place. Both collect() and toPandas() bring data into driver memory. A result that fits across a cluster may overwhelm the driver. Inspect a small sample or write distributed output when appropriate. PySpark DataFrame quickstart
Move the large rows—or copy the small lookup
- A
Shuffle join
Redistribute both inputs by key
- A
Network + disk
Exchange can dominate cost
- B
Broadcast join
Send the small catalog to workers
- B
Local matching
Keep the large input in place
Spark can process arriving data too
Our daily report processes a bounded set of records. Suppose the requirement changes: update totals as new records arrive.
Structured Streaming applies Spark SQL's structured-data model to incremental processing. Its default execution mode uses micro-batches, processing newly available data in small batches. Streaming work also introduces decisions about late records, retained state, and recovery. Structured Streaming guide
Treat delivery guarantees as an end-to-end property. Exactly-once results depend on supported sources and sinks, checkpointing, and the design of output operations. Arbitrary external side effects do not automatically become exactly-once because Spark performs the computation. Structured Streaming guide
Start with a correct batch calculation. Then ask how its meaning should change when records arrive late or processing restarts.
The wider Spark ecosystem
Spark also includes MLlib for machine learning and GraphX for graph processing. These are specialized paths to explore when a project needs them. Begin with DataFrames and SQL; you do not need to learn every library before building a useful pipeline.
How Databricks relates to Spark
Apache Spark is the open-source processing engine. Databricks provides a managed platform that incorporates Spark and adds platform capabilities around data work. Its runtime includes Spark alongside additional components and optimizations. You can learn or use Spark without choosing Databricks. Databricks Spark overview
Separating engine concepts from platform features helps when following tutorials. Partitions and shuffles belong to Spark's execution model; workspace interfaces and managed workflows depend on the environment you use.
When a simpler tool is enough
Before adopting Spark, define the problem you need to solve:
- Does an existing database already perform the calculation adequately?
- Can a single-machine tool handle the data within the required time?
- Is distributed processing worth the operational complexity?
- Will the team be able to diagnose slow or failed runs?
There is no universal file-size cutoff that answers those questions. Available memory, data shape, transformations, and the required turnaround time all matter. Benchmark a representative workload before committing to an architecture.
A practical learning path
Start with the activity example, then make one change at a time:
- Read a small file and inspect its schema.
- Add filters, derived columns, and grouped totals.
- Write the same calculation in SQL and compare the results.
- Use
explain()and the Spark UI to connect your code to execution. - Add a join, look for data movement, and investigate uneven tasks.
- Try Structured Streaming once the batch version is clear.
The goal is to explain your own pipeline: what each row represents, where work can run independently, where data must move, and where results end up. Once those questions make sense, Spark's terminology becomes much easier to navigate.
Source note
This original explainer was prompted by Data with Baraa's What is Spark? (Visual Explanation). The video's public title and chapter themes were verified, but its transcript and captions were unavailable during preparation. This article is therefore an independently written, documentation-grounded introduction, not a transcript adaptation or a claim to reproduce the video's full contents. Technical references are linked beside the relevant explanations above.