Data Engineering
8 articles in this topic.
PySpark Mental Model: Lazy DataFrames for Media Analytics
Learn the PySpark mental model with a synthetic streaming-media dataset: DataFrames, lazy transformations, actions, and reading a query plan.
PySpark Ingestion: Explicit Schemas and a Delta Bronze Table
Ingest synthetic playback JSON with explicit PySpark schemas, capture malformed records, and write an append-only Delta bronze table.
PySpark Window Functions: Viewer Sessions and Completion Rates
Use PySpark window functions to sessionize synthetic viewer events, join a title catalog, and compute watch time and completion rates.
Spark Performance: Shuffles, Partitions, and Broadcast Joins
A practical Spark performance guide using synthetic media data: shuffles, partition sizing, skew, broadcast joins, and adaptive query execution.
Spark Structured Streaming: Watermarks and Concurrent Viewers
Build Spark Structured Streaming windows and watermarks on synthetic playback events, with checkpoints and a per-minute heartbeat activity proxy.
Testing PySpark Pipelines: Data Quality Checks That Catch Bugs
Test PySpark transformations with small synthetic DataFrames, assertDataFrameEqual, and explicit data quality expectations for media events.
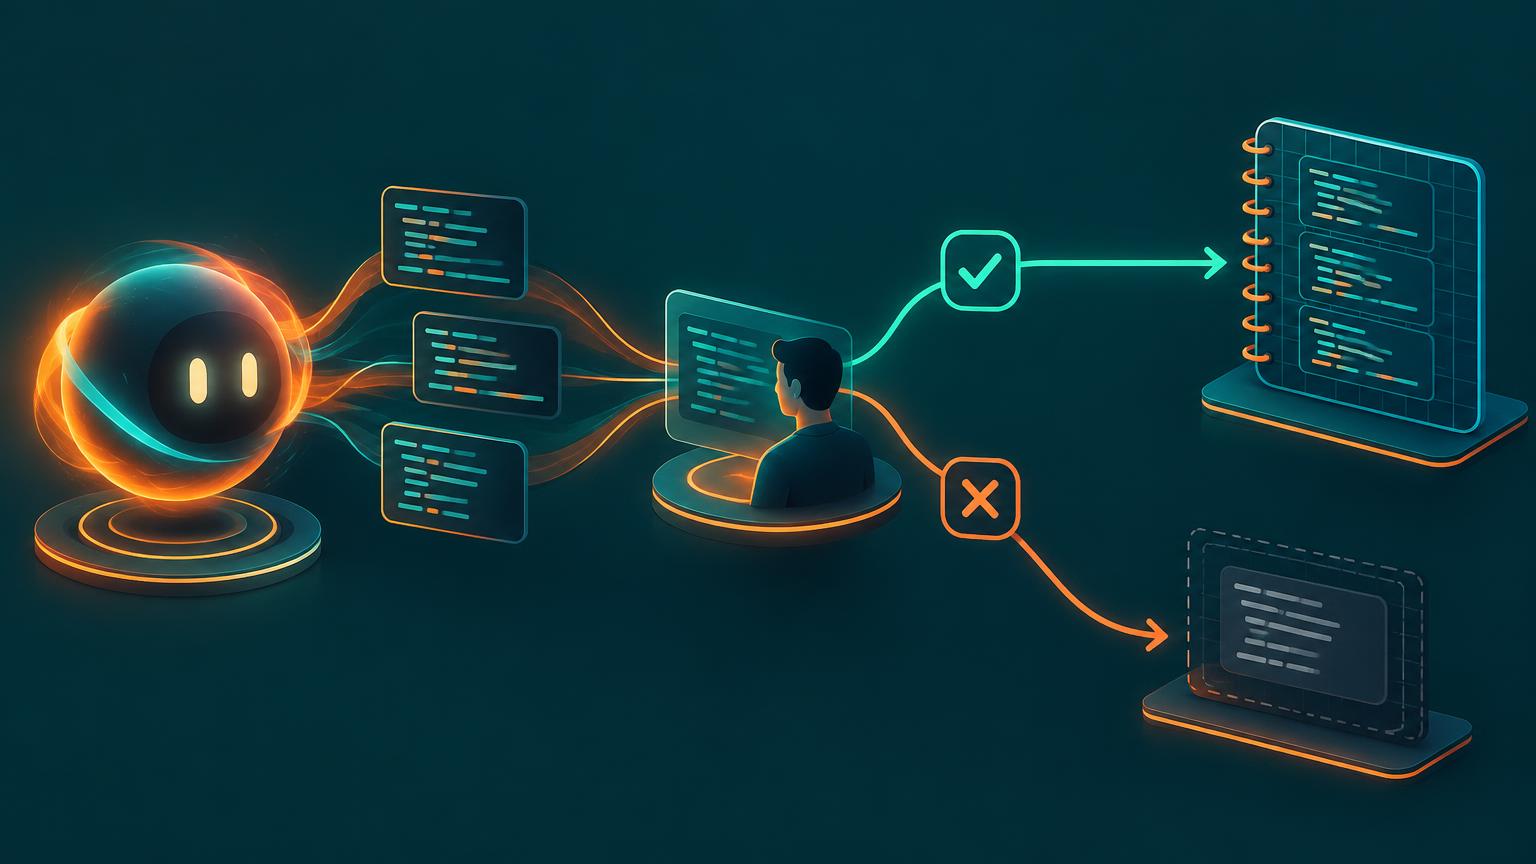
Databricks Genie Code for PySpark: A Review-First Workflow
A practical workflow for Databricks Genie Code with PySpark: clear prompts, Unity Catalog context, reviewing generated code, and verifying results.
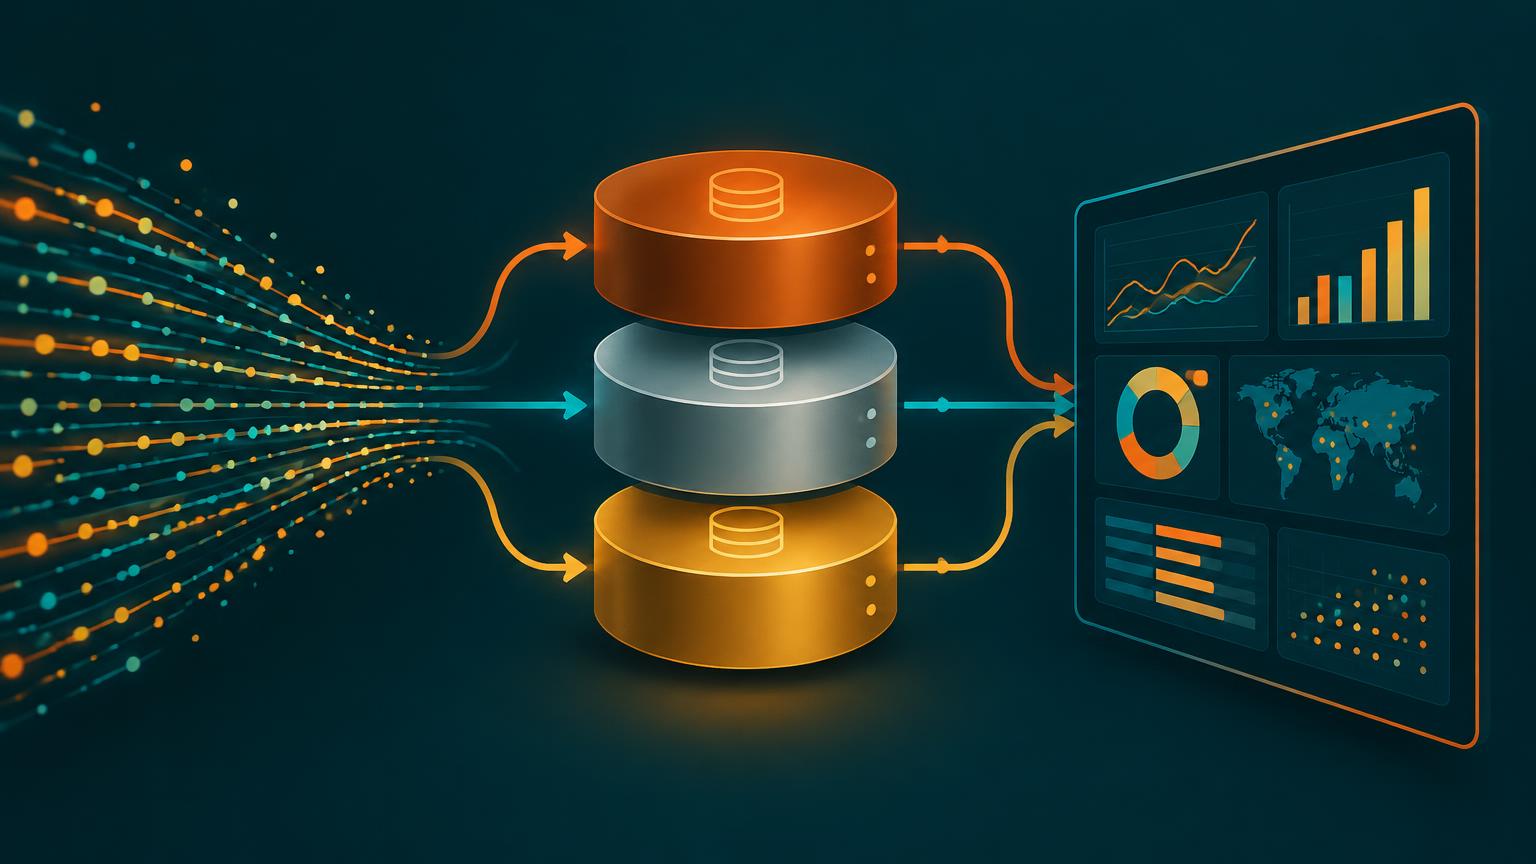
Capstone: An End-to-End Spark Medallion Pipeline for Media Data
Combine ingestion, sessionization, quality checks, and streaming into a bronze-silver-gold Spark pipeline on synthetic streaming-media data.
New posts, straight from Chris
A short note from me whenever a new article goes live — product engineering, AI workflows, IoT, indie apps, and engineering leadership. No spam, unsubscribe anytime.
By subscribing, you agree to our Privacy Policy. We do not share your email.