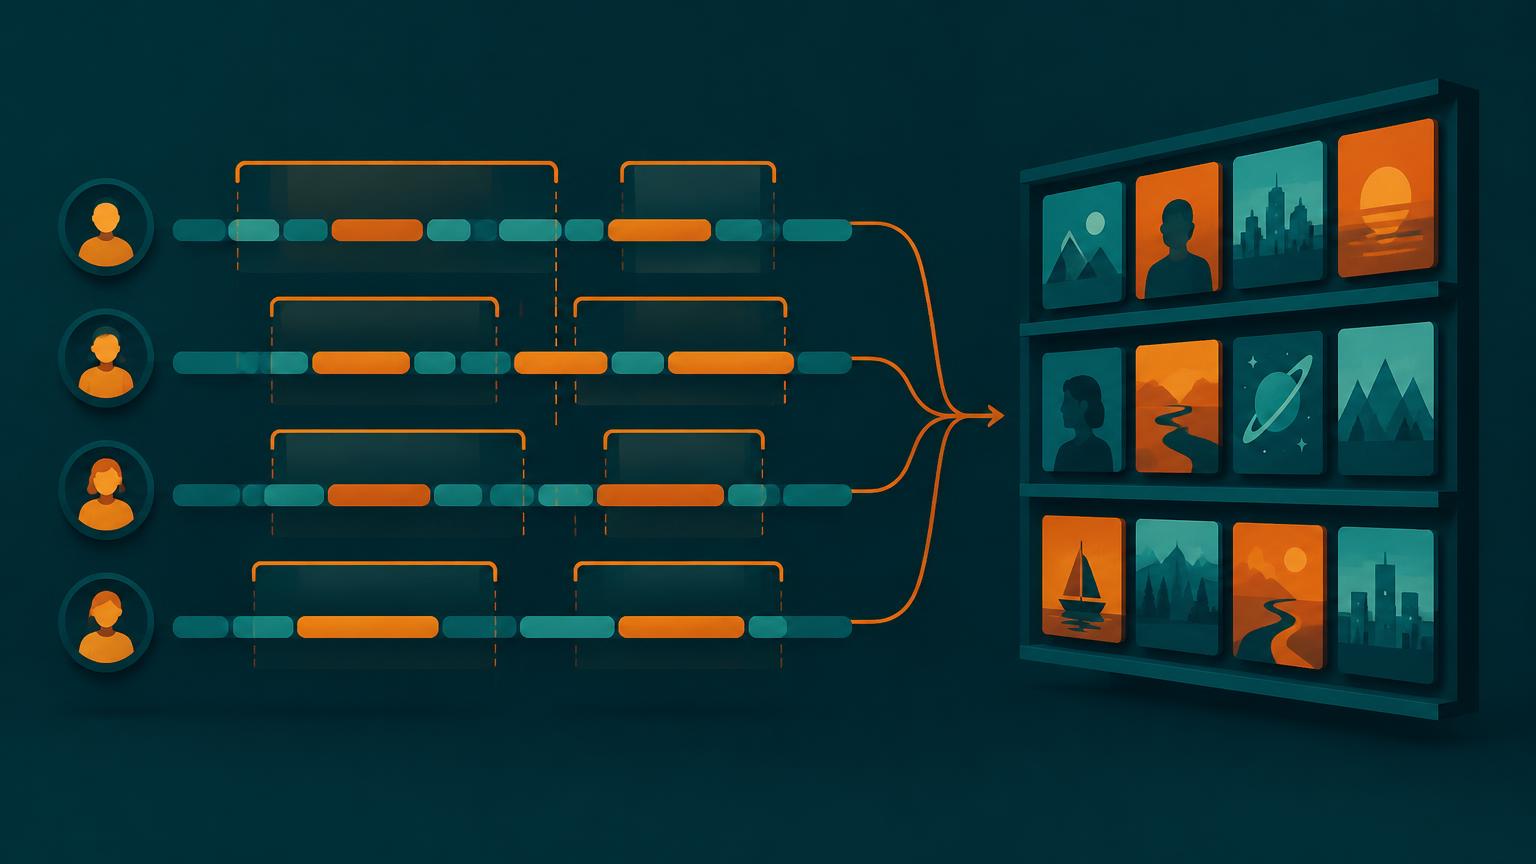
Raw events answer few business questions. People want sessions: how long someone watched in one sitting, what they finished, and which titles hold attention. Window functions are the core tool for that.
A synthetic title catalog
catalog.pyPython
1catalog = (2 spark.range(300).withColumnRenamed("id", "title_id")3 .withColumn("title_id", F.col("title_id").cast("int"))4 .withColumn("genre", F.element_at(5 F.array(*[F.lit(g) for g in ["drama", "comedy", "docs", "kids", "thriller"]]),6 (F.col("title_id") % 5 + 1).cast("int")))7 .withColumn("runtime_minutes", (F.col("title_id") % 90 + 22).cast("int"))8)Sessionize with lag
A new session starts when a viewer has been idle for more than 30 minutes. We compare each event to the previous one for that viewer, flag gaps, and take a running sum of the flags.
sessions.pyPython
1from pyspark.sql import Window2 3by_viewer = Window.partitionBy("viewer_id").orderBy(4 "event_ts", "title_id", "event_type", "watch_seconds")5GAP = 30 * 606 7sessions = (8 good9 .withColumn("prev_ts", F.lag("event_ts").over(by_viewer))10 .withColumn("new_session", F.when(11 F.col("prev_ts").isNull() |12 (F.col("event_ts").cast("long") - F.col("prev_ts").cast("long") > GAP), 113 ).otherwise(0))14 .withColumn("session_n", F.sum("new_session").over(15 by_viewer.rowsBetween(Window.unboundedPreceding, 0)))16 .withColumn("session_id", F.concat_ws("-", "viewer_id", "session_n"))17)Break timestamp ties with title_id, event_type, and watch_seconds where available. The gap boundary stays strict: exactly 1,800 seconds belongs to the same session; only a gap greater than 1,800 starts another.
Join and measure
metrics.pyPython
1session_titles = (2 sessions.groupBy("session_id", "viewer_id", "title_id")3 .agg(F.sum("watch_seconds").alias("watched"),4 F.max(F.col("event_type") == "complete").alias("completed"))5 .join(F.broadcast(catalog), "title_id")6)7 8genre_metrics = (9 session_titles.groupBy("genre")10 .agg(F.countDistinct("viewer_id").alias("viewers"),11 F.round(F.avg(F.col("completed").cast("double")), 3).alias("completion_rate"),12 F.round(F.sum("watched") / 3600, 1).alias("hours"))13 .orderBy(F.desc("hours"))14)Ranking is another common window: top three titles per genre by hours watched.
Top titles per genrePython
1by_genre = Window.partitionBy("genre").orderBy(F.desc("hours"))2top_titles = (3 session_titles.groupBy("genre", "title_id")4 .agg((F.sum("watched") / 3600).alias("hours"))5 .withColumn("rank", F.dense_rank().over(by_genre))6 .filter("rank <= 3")7)Exercises
- Change the session gap to 10 minutes. How does the session count change?
- Compute median session length per device using percentile_approx.
- Add a ratio of watched seconds to runtime and flag sessions above 1.0 as suspicious.
- Rewrite the top-titles query in Spark SQL and compare plans.
Official documentation