Most slow Spark jobs are slow for a small number of reasons: too much data moved between machines, partitions that are badly sized, or one key holding far more rows than the rest. Each is visible in the plan before you spend money.
Spot the shuffle
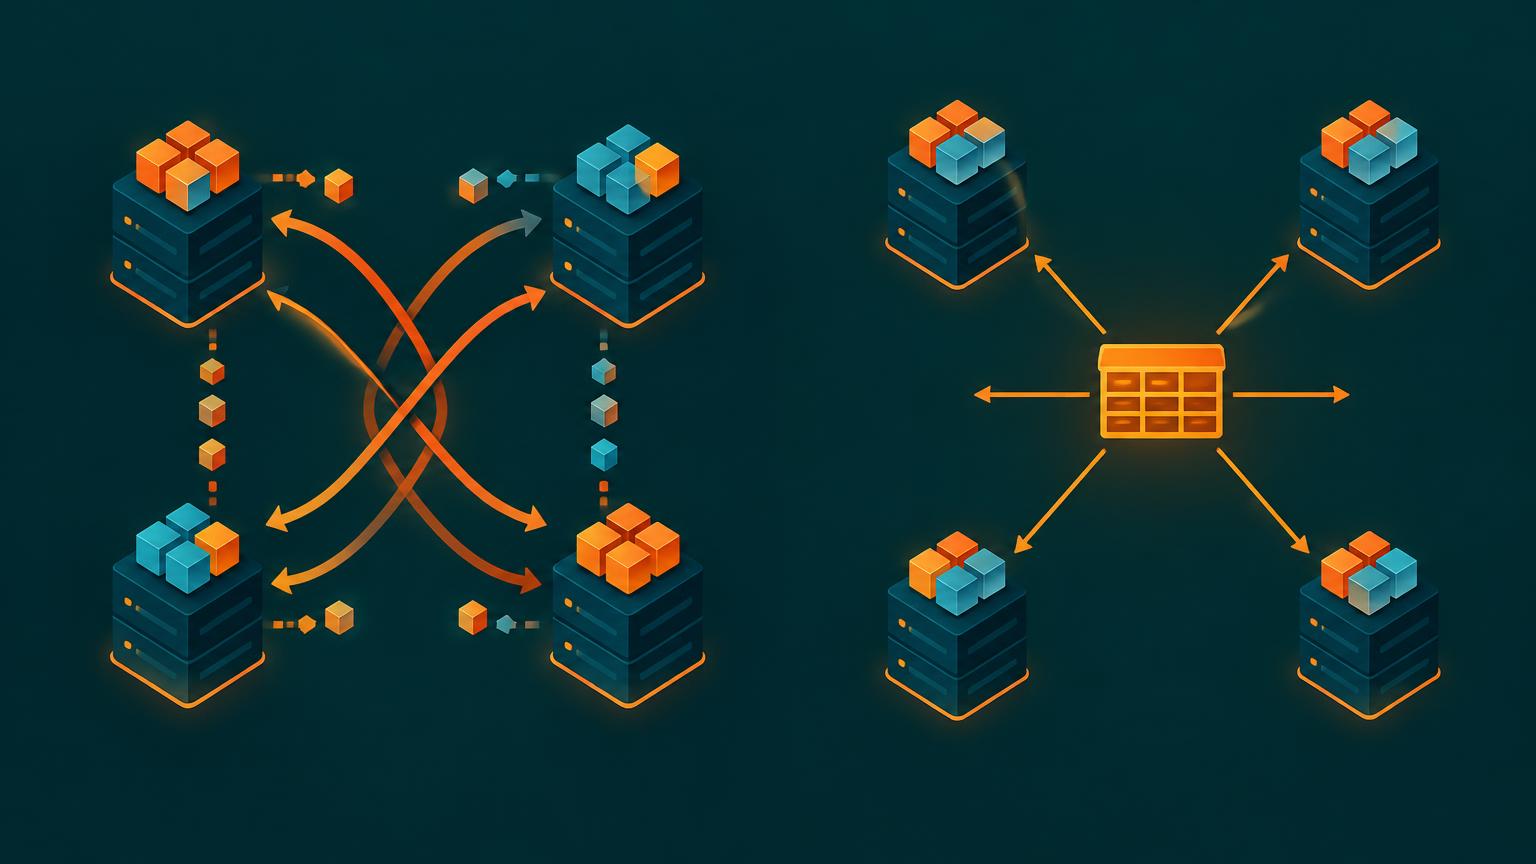
In explain() output, an Exchange node is a shuffle: rows are redistributed by key across the network. groupBy, join, distinct, and window partitions usually create one.
Find exchangesPython
1plan = genre_metrics._jdf.queryExecution().executedPlan().toString()2print(plan.count("Exchange"), "shuffles")3 4# Friendlier: open the SQL tab in the Spark UI after running an actionBroadcast small dimensions
The catalog has 300 rows. Shuffling 200,000 events to join it is wasteful; sending the small table to every executor avoids moving the large one.
Broadcast joinPython
1joined = events.join(F.broadcast(catalog), "title_id")2joined.explain() # look for BroadcastHashJoin, not SortMergeJoinSimulate skew
One viral titlePython
1skewed = events.withColumn("title_id",2 F.when(F.rand(seed=7) < 0.4, F.lit(42)).otherwise(F.col("title_id")))3 4# A salted aggregation spreads the hot key across buckets5SALT = 166salted = (7 skewed.withColumn("salt", (F.rand(seed=1) * SALT).cast("int"))8 .groupBy("title_id", "salt").agg(F.sum("watch_seconds").alias("s"))9 .groupBy("title_id").agg(F.sum("s").alias("watch_seconds"))10)| Setting | What it controls | Starting point |
|---|---|---|
| spark.sql.shuffle.partitions | Partitions after a shuffle | Let AQE coalesce; tune if tasks are tiny or huge |
| spark.sql.adaptive.enabled | Runtime re-planning | On (default in recent Spark) |
| spark.sql.adaptive.skewJoin.enabled | Splits skewed join partitions | On; verify in the plan |
| spark.sql.autoBroadcastJoinThreshold | Max size to auto-broadcast | Raise carefully; executors hold the copy |
Exercises
- Run the skewed aggregation without salt and find the straggler task in the Spark UI.
- Disable AQE, re-run the genre metrics, and compare partition counts.
- Force a sort-merge join on the catalog and compare the shuffle size with the broadcast version.
- Write a one-paragraph performance note explaining which fix you would ship and why.
Official documentation